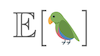
ep. The commands edsl and python -m edsl are equivalent entry points. An EDSL Agent describes a survey respondent; a coding agent is software that can use the CLI to build and run a study.
Install and discover commands
Install EDSL in your Python environment:ep info reports configuration diagnostics and redacts credentials. See Installation for environment setup.
Try a local example
Run these commands in a working directory where you want to save the example files. They create a survey and execute it with EDSL’s test model, which returns a fixed answer. This example requires no model credentials and makes no paid model calls; its output is test data. Create a question and save it as a survey:A test response. The completed responses are saved in test-results.ep; the run command returns execution metadata rather than response rows.
Read each command’s JSON response and check status before proceeding to the next command.
Read command responses
By default, operational commands write one JSON document to stdout. Diagnostics go to stderr, and output captured from lower-level operations may appear inwarnings. Help output from --help is plain text. Options that explicitly request raw output, such as --output - on object-creation commands, bypass the usual response envelope.
A successful response has this structure:
data contains command-specific information. When a command saves a file, inspect the returned save metadata for its path and format.
An error response has this structure; suggestion is included when available:
status, read warnings, and check the process exit code. Do not extract identifiers or URLs from progress messages. For example:
Create and validate study objects
Prefer.ep packages for objects you want to save, inspect, reuse, or share. The CLI also accepts serialized JSON for many commands. A Jobs object combines the survey with its agents, scenarios, and models.
Inspect schemas before constructing serialized objects by hand:
add-question updates the survey package in place. A job built earlier retains its saved survey, so rebuild the job to include the new question. Use ep agents create --help and ep scenarios create --help for creating respondent profiles and scenario data from files.
If validation fails, correct the reported problem before running the object.
Run with language models
For hosted execution, configure an Expected Parrot account and API key as described in Managing Keys. Check authentication and connectivity:MODEL_NAME below with a model returned by the catalog. These commands build and estimate a job; the final command runs it and may incur model usage costs:
.ep for a Results package or .json for serialized data.
To disable remote inference, add --local. This runs execution on your machine but can still call a model provider over the network and incur charges. Provider credentials or a configured local model server are required for real model calls. See Connect to your own model server for endpoint configuration.
When overriding a saved job, --agent_list, --scenario_list, and --model_list replace the corresponding component. --model replaces the model list with one model; it cannot be combined with --model_list.
Submit a background job
Use background execution for long remote jobs:data.meta.remote_job when available. Read its job_uuid and use that value in follow-up commands. Replace JOB_UUID below with the returned identifier:
--background alone returns before responses are ready. Do not combine --background with --output unless you also use --wait.
Collect human responses
After configuring Expected Parrot authentication, you can publish the saved survey for human participants:humanize create creates a hosted survey. Read the returned survey identifier and respondent URL from the JSON response. Share the respondent URL with participants when you are ready to collect responses.
Replace HUMAN_SURVEY_UUID with the returned identifier to inspect the survey and save responses:
--jobs. Jobs used for human surveys must not include models. If they contain scenarios, supply --scenario_method; use ep humanize create --help to see the available assignment methods.
See Humanize for survey configuration and Prolific studies for participant recruitment.
Inspect and export saved responses
Use results commands on saved files:--column for multiple columns; do not pass a comma-separated list. Inspect available columns before selecting them. Use a bounded select to review responses and export to save larger datasets. Results queries support .ep, .json, and .json.gz files.
Automation conventions
- Discover commands and schemas from the installed version before generating inputs.
- Validate inputs, check every response’s
status, and readwarningsbefore continuing. - Keep credentials out of logs and shared files. Use the configuration described in Managing Keys.
- Use saved objects and returned identifiers to continue work. A background submission is not a completed run.
- Pass explicit pagination, for example
ep jobs list --page 1 --page_size 20, and inspect returned pagination metadata. - Retry remote operations only when doing so will not duplicate work. Check job status before submitting another run.
- Obtain explicit user direction before destructive actions such as
ep deleteorep jobs cancel; both require--yes.
Exit codes
Use the JSON error’s
code, message, and optional suggestion to decide the next step. For example, correct flags after USAGE_ERROR, inspect schemas after VALIDATION_ERROR, and check credentials after AUTH_ERROR.